Does Physical Intelligence Scale with Data?
Current evidence on robot scaling laws, open questions, and why scaling laws matter for the safety of physical AI.
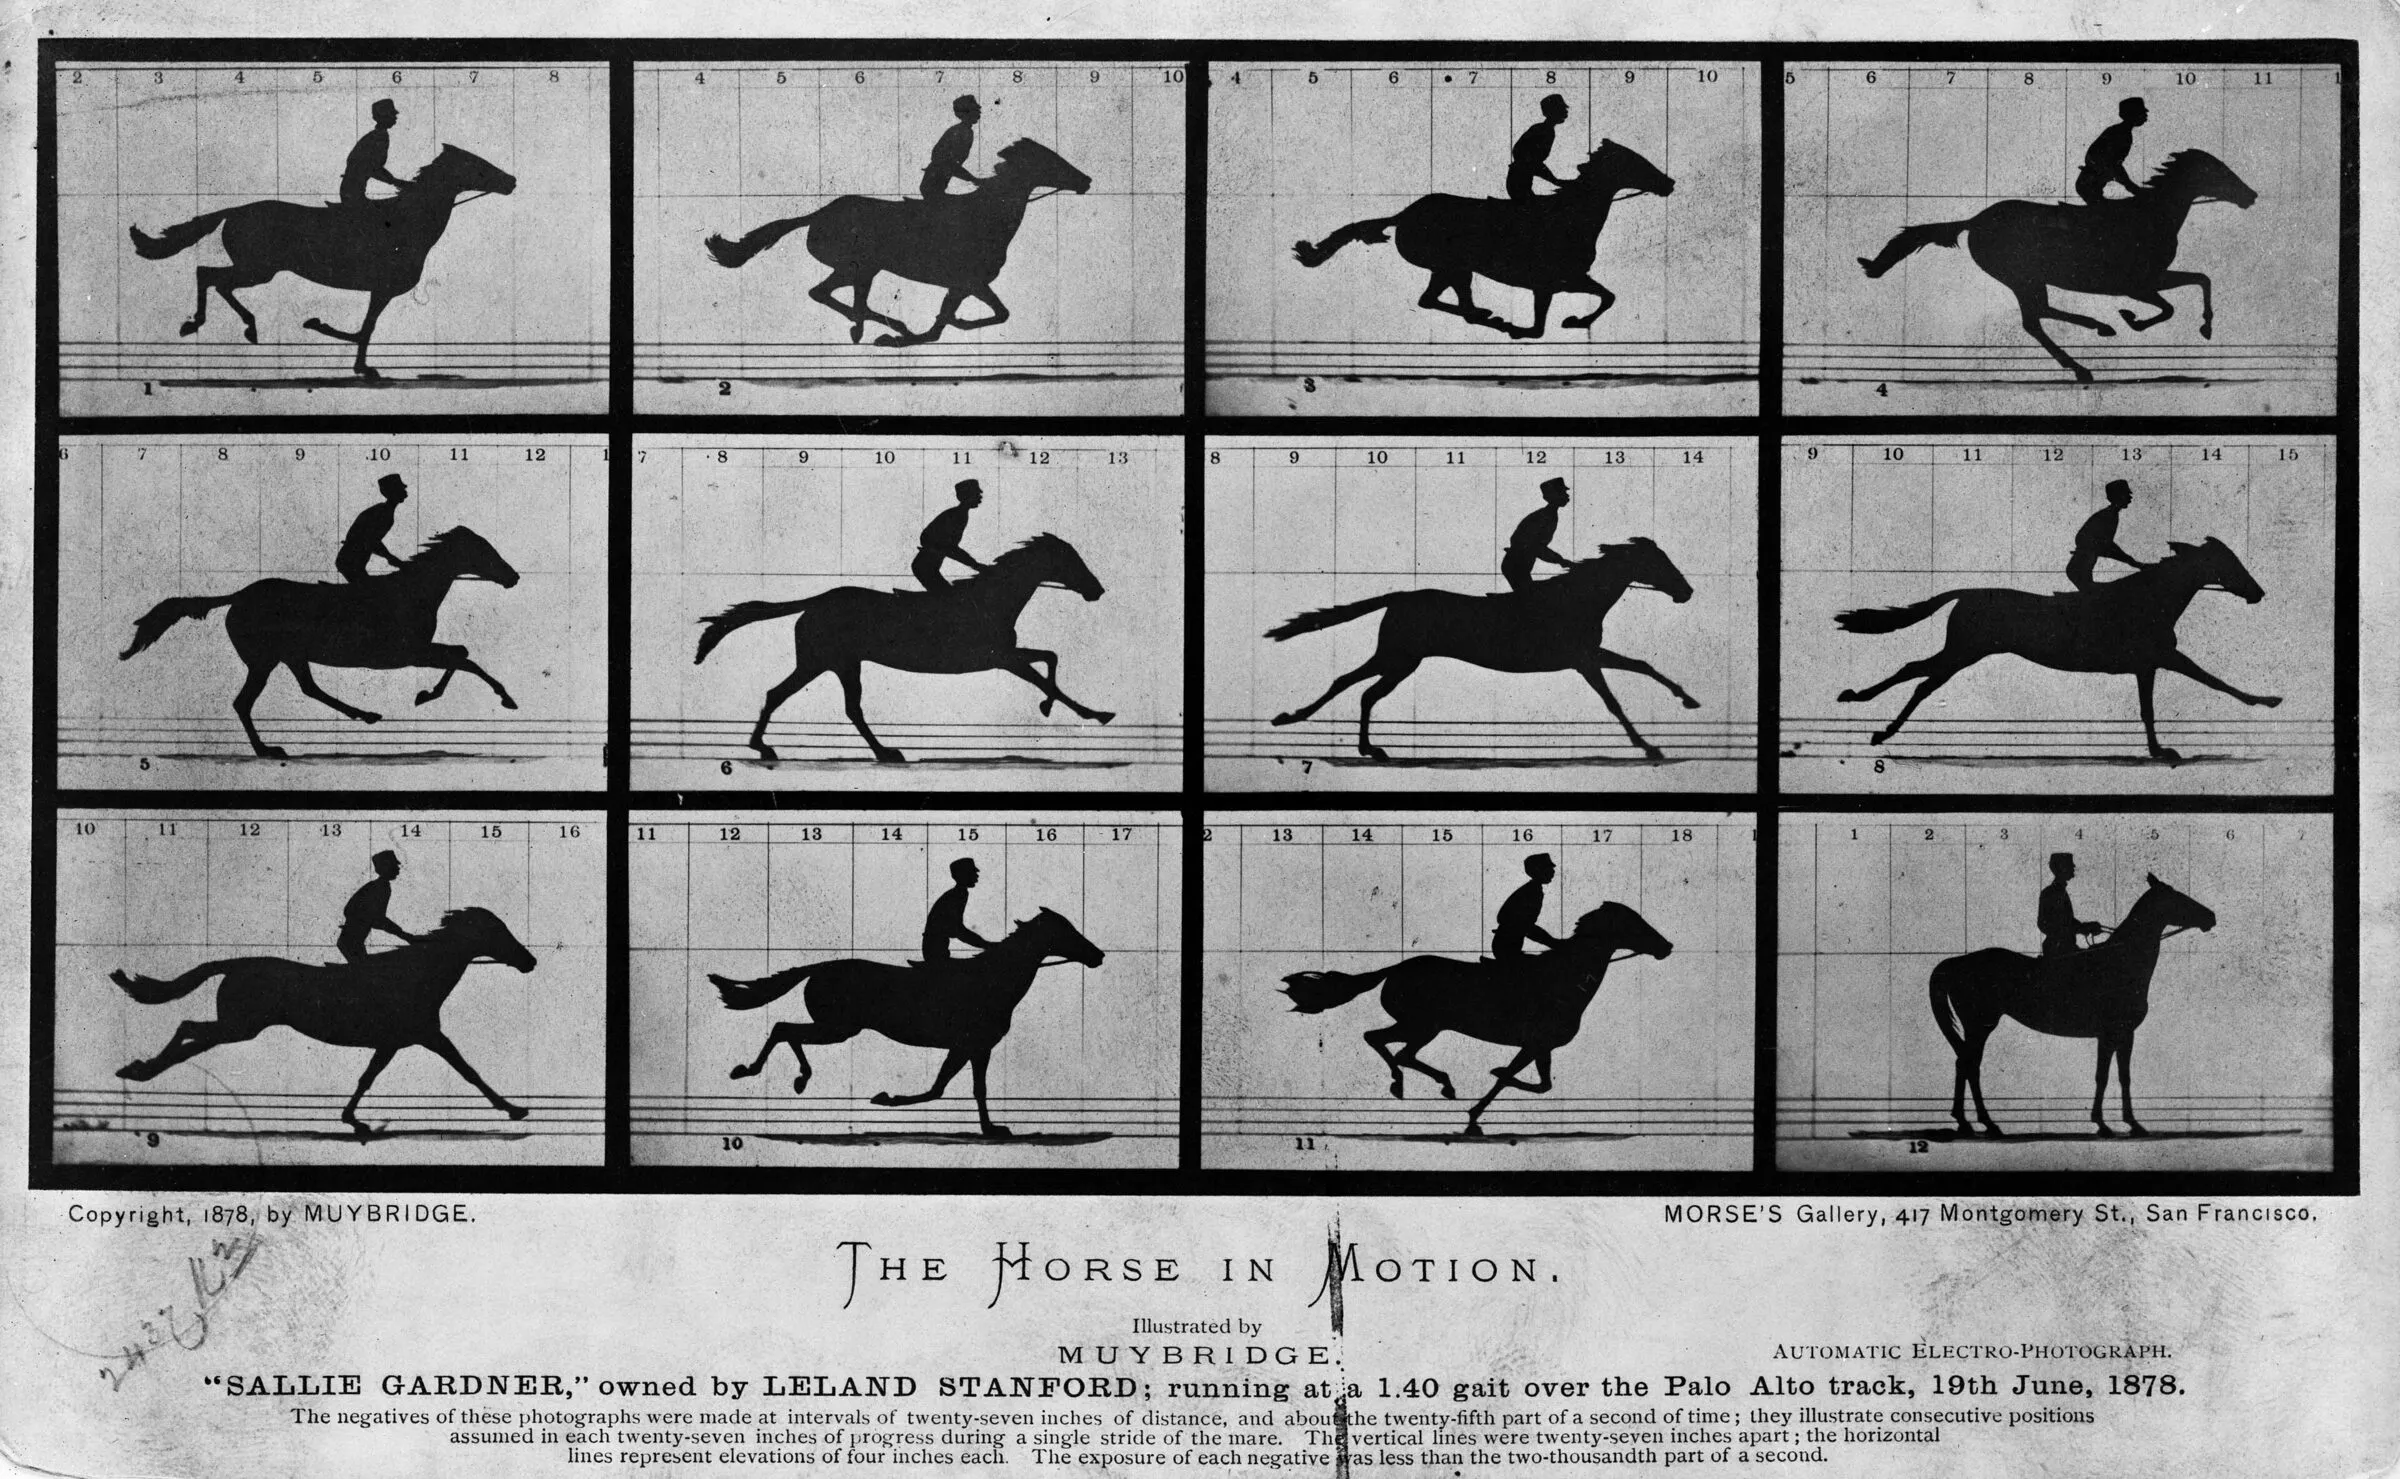
Eadweard Muybridge, The Horse in Motion (1878): the first motion-capture dataset. Public domain, via Wikimedia Commons.
I spend a lot of time these days thinking about the future of robot intelligence. To make good decisions about what models to test and what kinds of safety technologies to develop, I often find myself wishing for a crystal ball that could tell me what robot brains in 1, 3 or 10 years will look like. Given the lack of oracles in the world, we have to fall back on our intuitions and empirical learnings from the past. One such intuition is that we may be able to make predictions about AI by decomposing it into three necessary components: Algorithms, hardware, and data. In robotics, as in LLMs, these are not independent: Certain types of learning algorithms may need significantly larger amounts of data than others, and the availability and properties of certain types of hardware (such as efficient GPUs) may make some algorithms viable that were previously not.1
Scaling laws are approximative models that aim to explain how model capabilities increase as a function of data, hardware, and other parameters such as model size (for monolithic neural architectures). In LLMs, neural scaling laws have shown that loss falls as a smooth power law in model size, data and compute (Kaplan et al., 2020), and that for a fixed compute budget, model size and training data should be scaled in equal proportion (Hoffmann et al., 2022, “Chinchilla”). In robotics, there are no established scaling laws yet; in fact, the robotics community is heavily debating the respective importances of algorithms, data and hardware, and remains divided along these lines. In the language domain, the quantity, quality and diversity of data has been identified as the primary driving factor of model intelligence.2 In robotics, the role of data is hotly debated. The remainder of this post is an attempt to answer the question to what degree robotics capabilities are bottlenecked by data, and in what ways - and to show that there are crucial ways in which algorithmic innovations and new hardware can fundamentally change the way physical intelligence scales with data.
Empirical Evidence
Scaling Studies find Power Laws
A few recent studies show that, for a given architecture and set of hardware capabilities, the performance of physical AI models scales with data. One study on imitation learning (Lin et al., 2024) finds that generalisation to new objects and environments follows a power law in the number of distinct environments and objects, with diminishing returns after about 50 demonstrations per environment. This echoes findings in the LLM literature that diversity matters more than the raw volume of data (Muennighoff et al., 2023). In a study on games (a form of “virtual embodiment” in which physical AI architectures can be studied well), Pearce et al. (2024) likewise find that scaling laws for agents and world models resemble LLM-style power laws. This holds both for world-modelling (predicting future states of the world) and behaviour-cloning (generating the next action given a demonstration) loss. The coefficients depend heavily on the tokeniser and architecture, indicating that such algorithmic choices don’t fundamentally impact scaling laws. The same power-law scaling laws have been found in a meta-analysis of studies on robot learning (Sartor & Thompson, 2024).
VLA Training Benefits from Diversity
The first large-scale, cross-embodiment dataset in physical AI was Open X-Embodiment (2023). It was used to train the RT-X model on pooled data from 20+ robots. Experiments show that training on cross-embodiment data from multiple different robots beats training on each robot alone, mostly at larger model sizes, echoing that diversity matters beyond tasks and environments. π0.5 (Physical Intelligence, 2025) shows that the model’s zero-shot generalization ability (performance in unseen environments) rises steadily with the number of distinct training environments. At around 100 it approaches the model’s performance in homes it was trained in, indicating that zero-shot generalization, for transformer-based architectures, is a function of data diversity. GEN-0 (Generalist AI, late 2025) claims clear scaling laws from about 270k hours of real manipulation data, and reports that scaling with data is conditional on model size: small models stop improving as data grows, while larger ones keep improving. With GEN-1 and GEN-1.5, they show that model performance keeps increasing as the amount of data is increasing, and is subject to phase shifts similar to those observed in LLMs (Wei et al., 2022), where model performance suddenly jumps and learning continues at a qualitatively higher level of capability. (Whether such jumps are real or an artefact of the evaluation metric is itself debated.)
What’s missing?
It looks as if the scaling laws of physical AI may strongly resemble those of language models: Dataset size and, crucially, data diversity matter, and training on additional data can unlock qualitative changes in model performance. What, then, is driving the remaining uncertainty around physical AI scaling laws?
The data gap
LLMs train on text that would take a person roughly 100,000 years to read. The largest robot datasets, by contrast, are thousands to hundreds of thousands of hours. Ken Goldberg called this the 100,000 year gap: Web-scale data pairing vision with actuator data simply does not exist yet, and more efficient methods of data collection are required before this gap can be closed. According to this view, the current paradigms of data generation do not provide sufficient amounts of data on a sufficiently short timescale, as teleoperation is too slow and reinforcement learning in simulation yields data that is only close to, but not quite representative of, real-world data. Goldberg and others propose to rely more on real-world robots collecting data in deployment, creating a data flywheel starting from simple tasks and bootstrapping more complex capabilities to collect data for more complex use cases, etc.
Rodney Brooks makes an interesting case for a different type of data gap. He argues that for every breakthrough in machine learning to date (speech to text, vision, language models), the processing that makes the data learnable came from long-standing technologies built for other purposes (e.g. the internet and digital signal processing). He proposes that no such technological precedent exists for tactile data: “We do not have such a tradition for touch data… We as a species have not developed technologies to capture touch, to store touch, to transmit touch over distances and time.” Brooks makes a case for a hardware bottleneck to data collection, as there is no current technological equivalent to the human hand with a comparable density of tactile sensors. Brooks’ model of robot learning being limited by tactile hardware hinges on the question of how many real-world tasks are actually bottlenecked by dexterity rather than cognitive abilities, and whether dexterity can be bootstrapped by relying on cross-modal learning that compensates for lower tactile resolution by use of language and image pretraining.
The epistemic gap
Given current studies on robot scaling laws, it is difficult to make robust assessments of the impact of data on real-world robot capabilities. Most studies measure offline loss or success on narrow benchmarks, and offline action loss is known to predict real-world success poorly (Mandlekar et al., 2021). No one has published a Chinchilla-style compute-optimal law for real-robot success. A study for real-world robot scaling laws would have to satisfy several additional desiderata:
- The outcome is real-world task success, not validation loss. Offline loss is known to be a poor predictor of how a policy performs when actually running on a robot. Success rates are also noisy and expensive to measure, as it involves physical trials on real hardware.
- Model size, data and compute are varied jointly on real robot data. Most studies vary one factor, or they vary data diversity, which is not a single number the way token count is.
- The hardware bottleneck is not compute, but sensor and actor hardware. Large, cross-modal, cross-embodiment datasets aggregating different sensor modalities such as vision, fingertip haptics, end-effector forces and torques, joint states and other modalities such as temperature don’t exist yet. Given how the learning curriculum of human babies is fundamentally cross-modal (Smith & Gasser, 2005), it could be that we have not yet studied the right kinds of data.
On the impact of cross-embodiment training, the evidence is mixed and additional studies are required: Several groups (Octo, OpenVLA and others) report that training on other robots’ data sometimes makes things worse, especially at small scale. I’m skeptical, however, that this is a meaningful finding, as the scale limitation may simply be overcome by larger models and that it is likely to only hold for the current family of (GPT-style) neural architectures, which may well change in the future.
Implications for Physical AI Safety
I have written about the risks of advanced physical AI in more detail in Building Safe Physical AI. Here, I focus on what the scaling question means for safety.
Studies on data requirements for safety training are missing. Safe deployment of intelligent robots requires very high success rates on the long tail of rare situations. There is almost no evidence on how failure rates scale with data, as opposed to average success rates. Robustness studies keep finding that current vision-language-action models are brittle to small changes such as camera angles, lighting, wording of the instruction, and distractor objects (Fei et al., 2025). Safety post-training of VLA models is currently only done in natural language, and current safety training datasets for embodied tasks (e.g. SafeVLA) consider only narrow definitions of safety that are unlikely to hold up to the kinds of open-ended situations real-world robots will face.
Data may be a good predictor of timelines to certain critical capabilities. If physical AI is primarily bottlenecked by data, the question of when large capability improvements are to be expected is determined by when a critical mass of data is reached. There is evidence from LLMs that such capability improvements are step functions (e.g. evidenced in the training curves of GEN-1.5). Tracking the adoption of technologies that can make fundamentally new kinds of data available, such as AR glasses (Ego-Exo4D, EgoMimic) or IoT devices, as well as deployments of intelligent robots that can generate data flywheels, may be highly informative for forecasting when such step changes in capabilities are likely to emerge across the industry.
How is the availability of powerful non-physical AI changing these calculations? Powerful LLMs and VLMs trained on web-scale data can dramatically accelerate robotics research at the algorithm level, and algorithms matter considerably. Convolution, attention and diffusion made breakthroughs in computer vision, natural-language processing and video generation possible and computationally tractable. LLM-uplifted science can find new inductive biases for physical AI that can dramatically reduce the amount of data needed. This introduces dramatic variability in forecasting models, as it is much harder to forecast such algorithmic innovation than e.g. the amount of available embodied data.
Footnotes
-
In the case of neural networks, algorithmic advances such as backpropagation, convolution and attention combined with hardware acceleration on GPUs made training on web-scale data, and the resulting exponential gains in model capabilities, possible. ↩
-
There is important nuance to be considered. As the amount of easy-to-mine web-scale text data is being exhausted, frontier labs are looking to acquire data from new places, such as physical books. Algorithmic advances to obtain higher-quality data, such as RLHF and, recently, self-supervised reinforcement learning on coding tasks (DeepSeek-R1), have driven capability improvements. Algorithmic innovations at the model level, such as mixture-of-experts architectures and chain-of-thought reasoning, become increasingly important as high-quality, diverse data becomes increasingly difficult to obtain at the margin. ↩